Kaggle / October 2026
Airline Satisfaction Prediction
An ongoing tabular classification project predicting airline passenger satisfaction, with reproducible folds, audited predictions, and ensemble evaluation.
Ongoing
- Public rank
- 21
- ROC AUC
- 0.96213
As of 23 Oct 2026 View leaderboard ↗
Public leaderboard
The challenge
My approach
Solution notes — reviewed 23 October 2026. Methods, local experiments, and competition standings are identified separately.
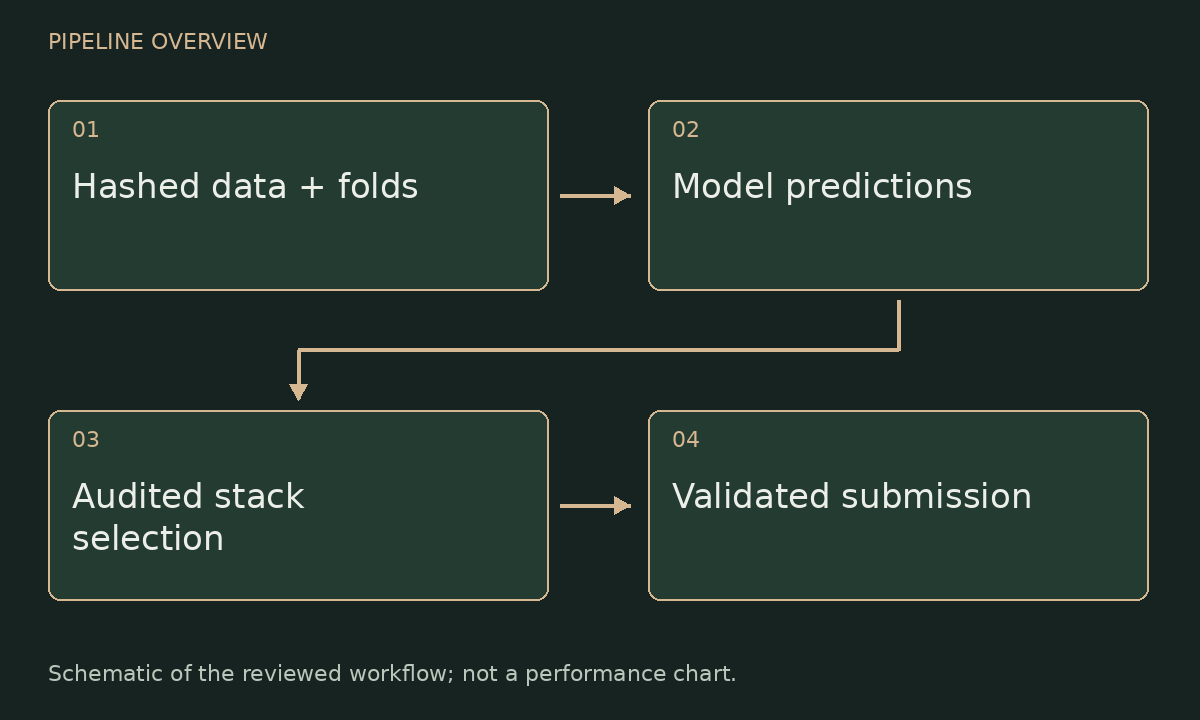
Open pipeline diagram at full size
Start with an auditable baseline
This ongoing Playground Series S6E10 project predicts passenger satisfaction with ROC AUC as the competition metric. The first recorded raw-feature LightGBM entry scored 0.95791 publicly. Before comparing more complex models, the project established input hashes, saved stratified folds, explicit target mapping, and checks on submission columns, IDs, ordering, and finite probability values.
From boosting to additional prediction sources
The local scripts explore boosting ensembles, stacking, engineered distance and target-encoding features, and tabular foundation-model predictions. One later line uses TabDPT 1.3. These are separate experiments, not a claim that every candidate entered the final stack. An ensemble is useful when a member contributes information that the current predictions miss; a new architecture alone is not evidence of that contribution.
Separating fit, stopping, and scoring
The project’s later audit found that an earlier inner cross-fit path used scored rows for early stopping. Subsequent pilots separated the rows used for fitting, early stopping, and evaluation. That correction is essential for honest model selection. Results produced under the older procedure should not be silently pooled with corrected evaluations, and the existence of a later audit does not retroactively validate every earlier experiment.
A concrete rejected pilot
The saved 21 October audit records a three-member pilot evaluated on 139,927 fold-zero rows. Its meta-model gain over the fixed anchor was about 0.000001987 AUC, below the predeclared 0.0001 threshold, with a negative lower confidence bound. The project closed that recipe rather than treating a positive point estimate as a reason to expand it. This is local validation evidence, not a Kaggle public score.
Inference and replay checks
The TabDPT work examined query batching against the implementation’s attention behavior and recorded separate inference and prediction artifacts. The broader workflow tracks model/configuration lineage, saved out-of-fold vectors, and candidate file hashes. A replay check is particularly valuable for a stack: reproducing the saved predictions from saved model state is stronger evidence than merely rerunning an AUC calculation on an existing vector.
Current result and remaining uncertainty
The public leaderboard snapshot checked on 23 October 2026 is rank 21 with ROC AUC 0.96213. The competition is still ongoing, and this score should not be called a final private result. Earlier progress files contain lower historical scores; they document the path of the project rather than replacing the newer live snapshot. The main lesson is to preserve evaluation boundaries and reject weak improvements even when the project is chasing a much higher rank.
Sources and provenance
The implementation and experiment records for this entry are private. This account summarizes the reviewed local code and logs without publishing private artifacts.